Staff / Senior Staff Machine Learning Engineer, Inference
$300k - $430k + equity
- Location
- San Francisco, Mountain View
- Workplace
- On-site or remote
- Employment
- Full-time
- Visa
- Visa Sponsorship Available
About this role
Who We're Looking For
A year ago, reliably working agentic systems and sub-second multimodal inference at scale barely existed. Nobody has a decade of experience here. So we're not screening for a resume template — we're looking for strong people from varied backgrounds who learn fast, thrive in ambiguity, and can show us what they've built, broken, and understood.
Experience We Find Useful
You don't need all of this. But you need enough to make a case.
- Inference Optimization. Deep understanding of modern serving frameworks and techniques like vLLM or TRT-LLM.
- Model Acceleration. Hands-on experience with quantization, distillation, caching strategies , continuous batching, paged attention, and speculative decoding.
- High-Performance Systems. Proficiency in C++, CUDA, Rust, or highly optimized Python. You know how to profile code and squeeze every ounce of performance out of NVIDIA GPUs.
- Distributed Systems & Scaling. Experience with Kubernetes, Ray, custom load balancing, multi-GPU/multi-node inference, and reliably handling thousands of concurrent connections.
- Public work. Non-trivial systems programming projects, open-source contributions to major inference engines, or deep-dive technical write-ups.
- Full-cycle ownership. You can take a model from the research team, containerize it, optimize its serving, and ensure it runs reliably in production.
- Background. PhD in CS, Physics, Math, or equivalent practical experience building backend or ML systems.
Who Thrives Here
- You don’t need a roadmap to start walking; you’re comfortable picking a direction and building the map as you go.
- You believe engineering isn't finished until it’s shipped and stable. You have a bias for impact over purely theoretical optimizations.
- You don't just ship code; you obsess over the why. You’re the first to question an architecture if you think there’s a better way to solve the core latency or throughput problem.
- You aren't satisfied with "the PM said so." You thrive on deep context and want to understand the fundamental logic behind every decision we make.
Apply to Inworld AI
They hire through Clera: your intro goes straight to the hiring team.
How it works
Confirm the fit
A few questions to make sure this role is the right shape for you. Two minutes.
Clera pitches you to the company
Clera writes the intro, sends it to the founder, and handles the back-and-forth.
A meeting lands on your calendar
When the company wants to meet, Clera gets the call on your calendar. You just show up.


Ask your AI about this role
It knows you. Clera gives it the role.
First time? Connect Clera once, about a minute.
https://mcp.getclera.comSign in with your Clera account. MCP docs
About Inworld AI
Inworld provides realtime AI models and infrastructure for games and media applications, powering interactive experiences for major companies like NVIDIA, Microsoft, and Ubisoft through proprietary speech and orchestration technology.
- Stage
- Series A
- Team size
- 11-50 people
- Founded
- 2021
- Industry
- AI
- Workplace
- On-site or remote
- Locations
- San Francisco, CA, United States; Mountain View, CA, USA; Remote (United States)
- Open roles
- 3
Know someone who'd fit?
Earn $5,000 per hire
Culture & values
- Fast-paced and ownership-driven culture where things move quickly and people operate with high degree of autonomy
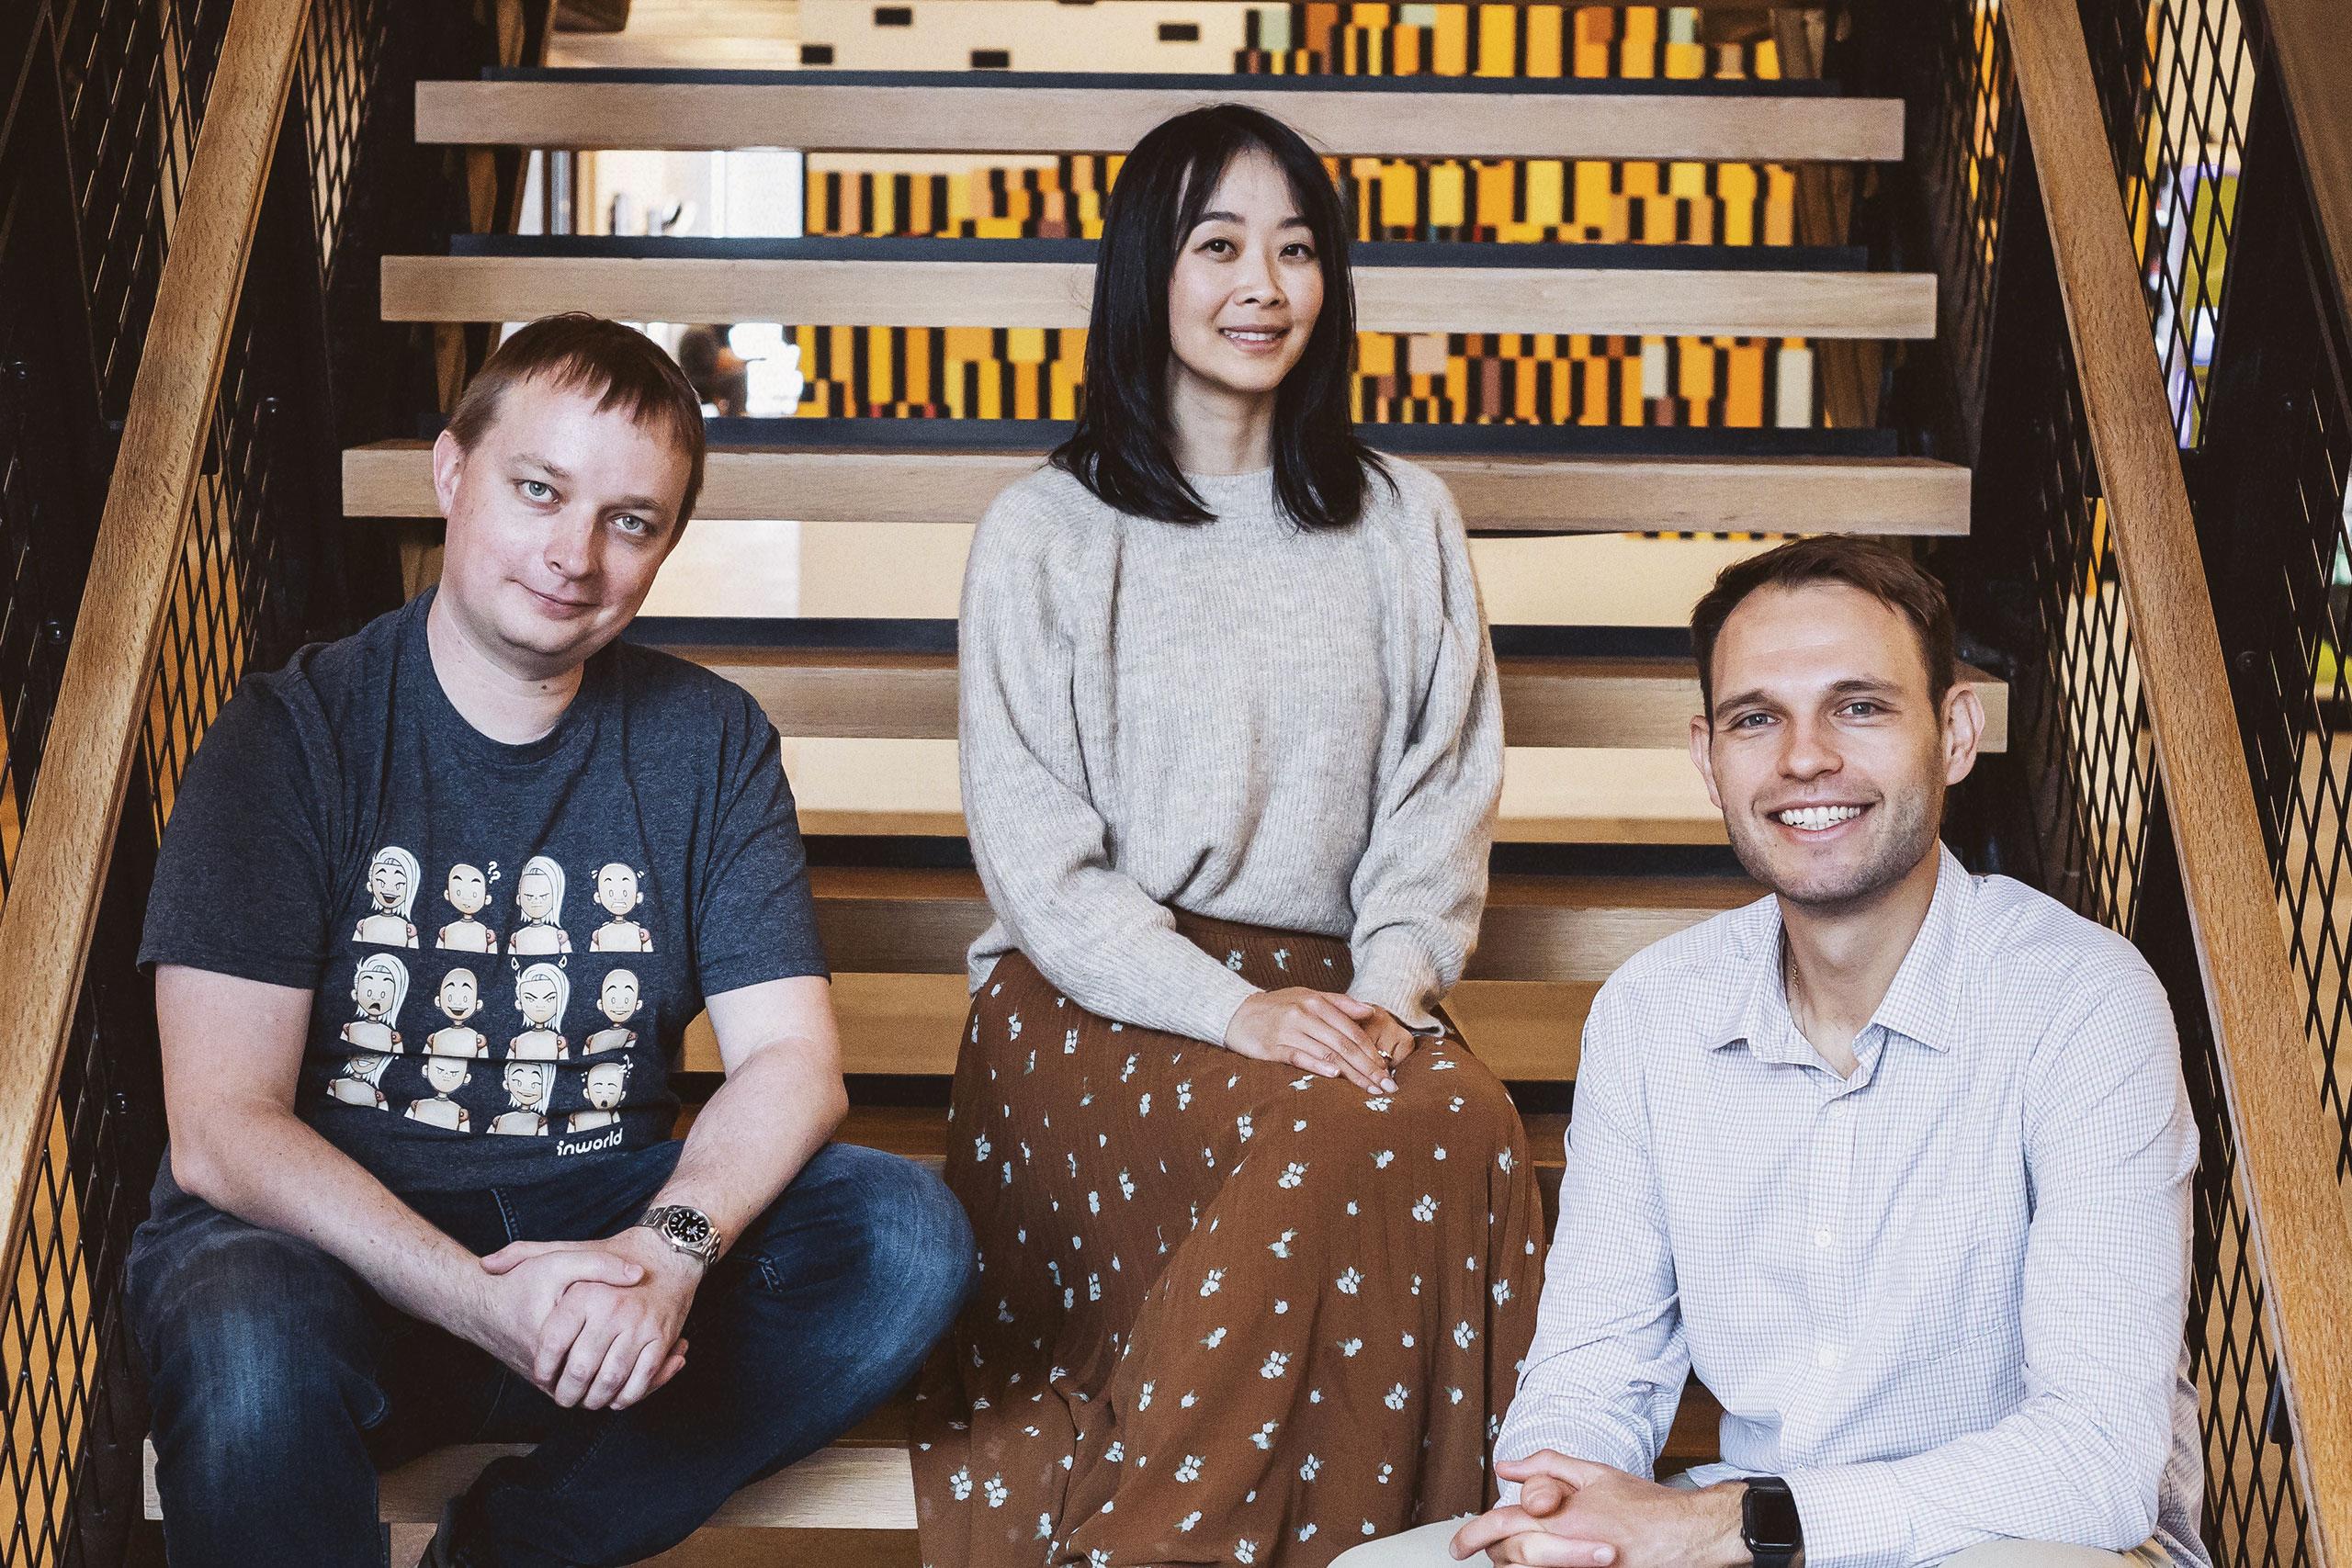
- Tight-knit group of roughly 105 people including researchers, engineers, and go-to-market operators
- Everyone wears multiple hats due to small team size relative to company growth
- Direct access to senior leadership and CEO by design, not through layers of management
- Company pays close attention to employee growth trajectory, promotions, and expanded impact over time
- Stagnation is viewed as a red flag internally
- Team rewards people who push themselves and the company forward
- Startup-minded approach with real systems and processes in place, moving with urgency and adaptability of early-stage company
- Culture values people comfortable with ambiguity, energized by change, and able to work without large support structures
- Culture of transparency and care with high degree of integrity and mutual respect
- AI-native by default culture where team actively uses AI tools in day-to-day work
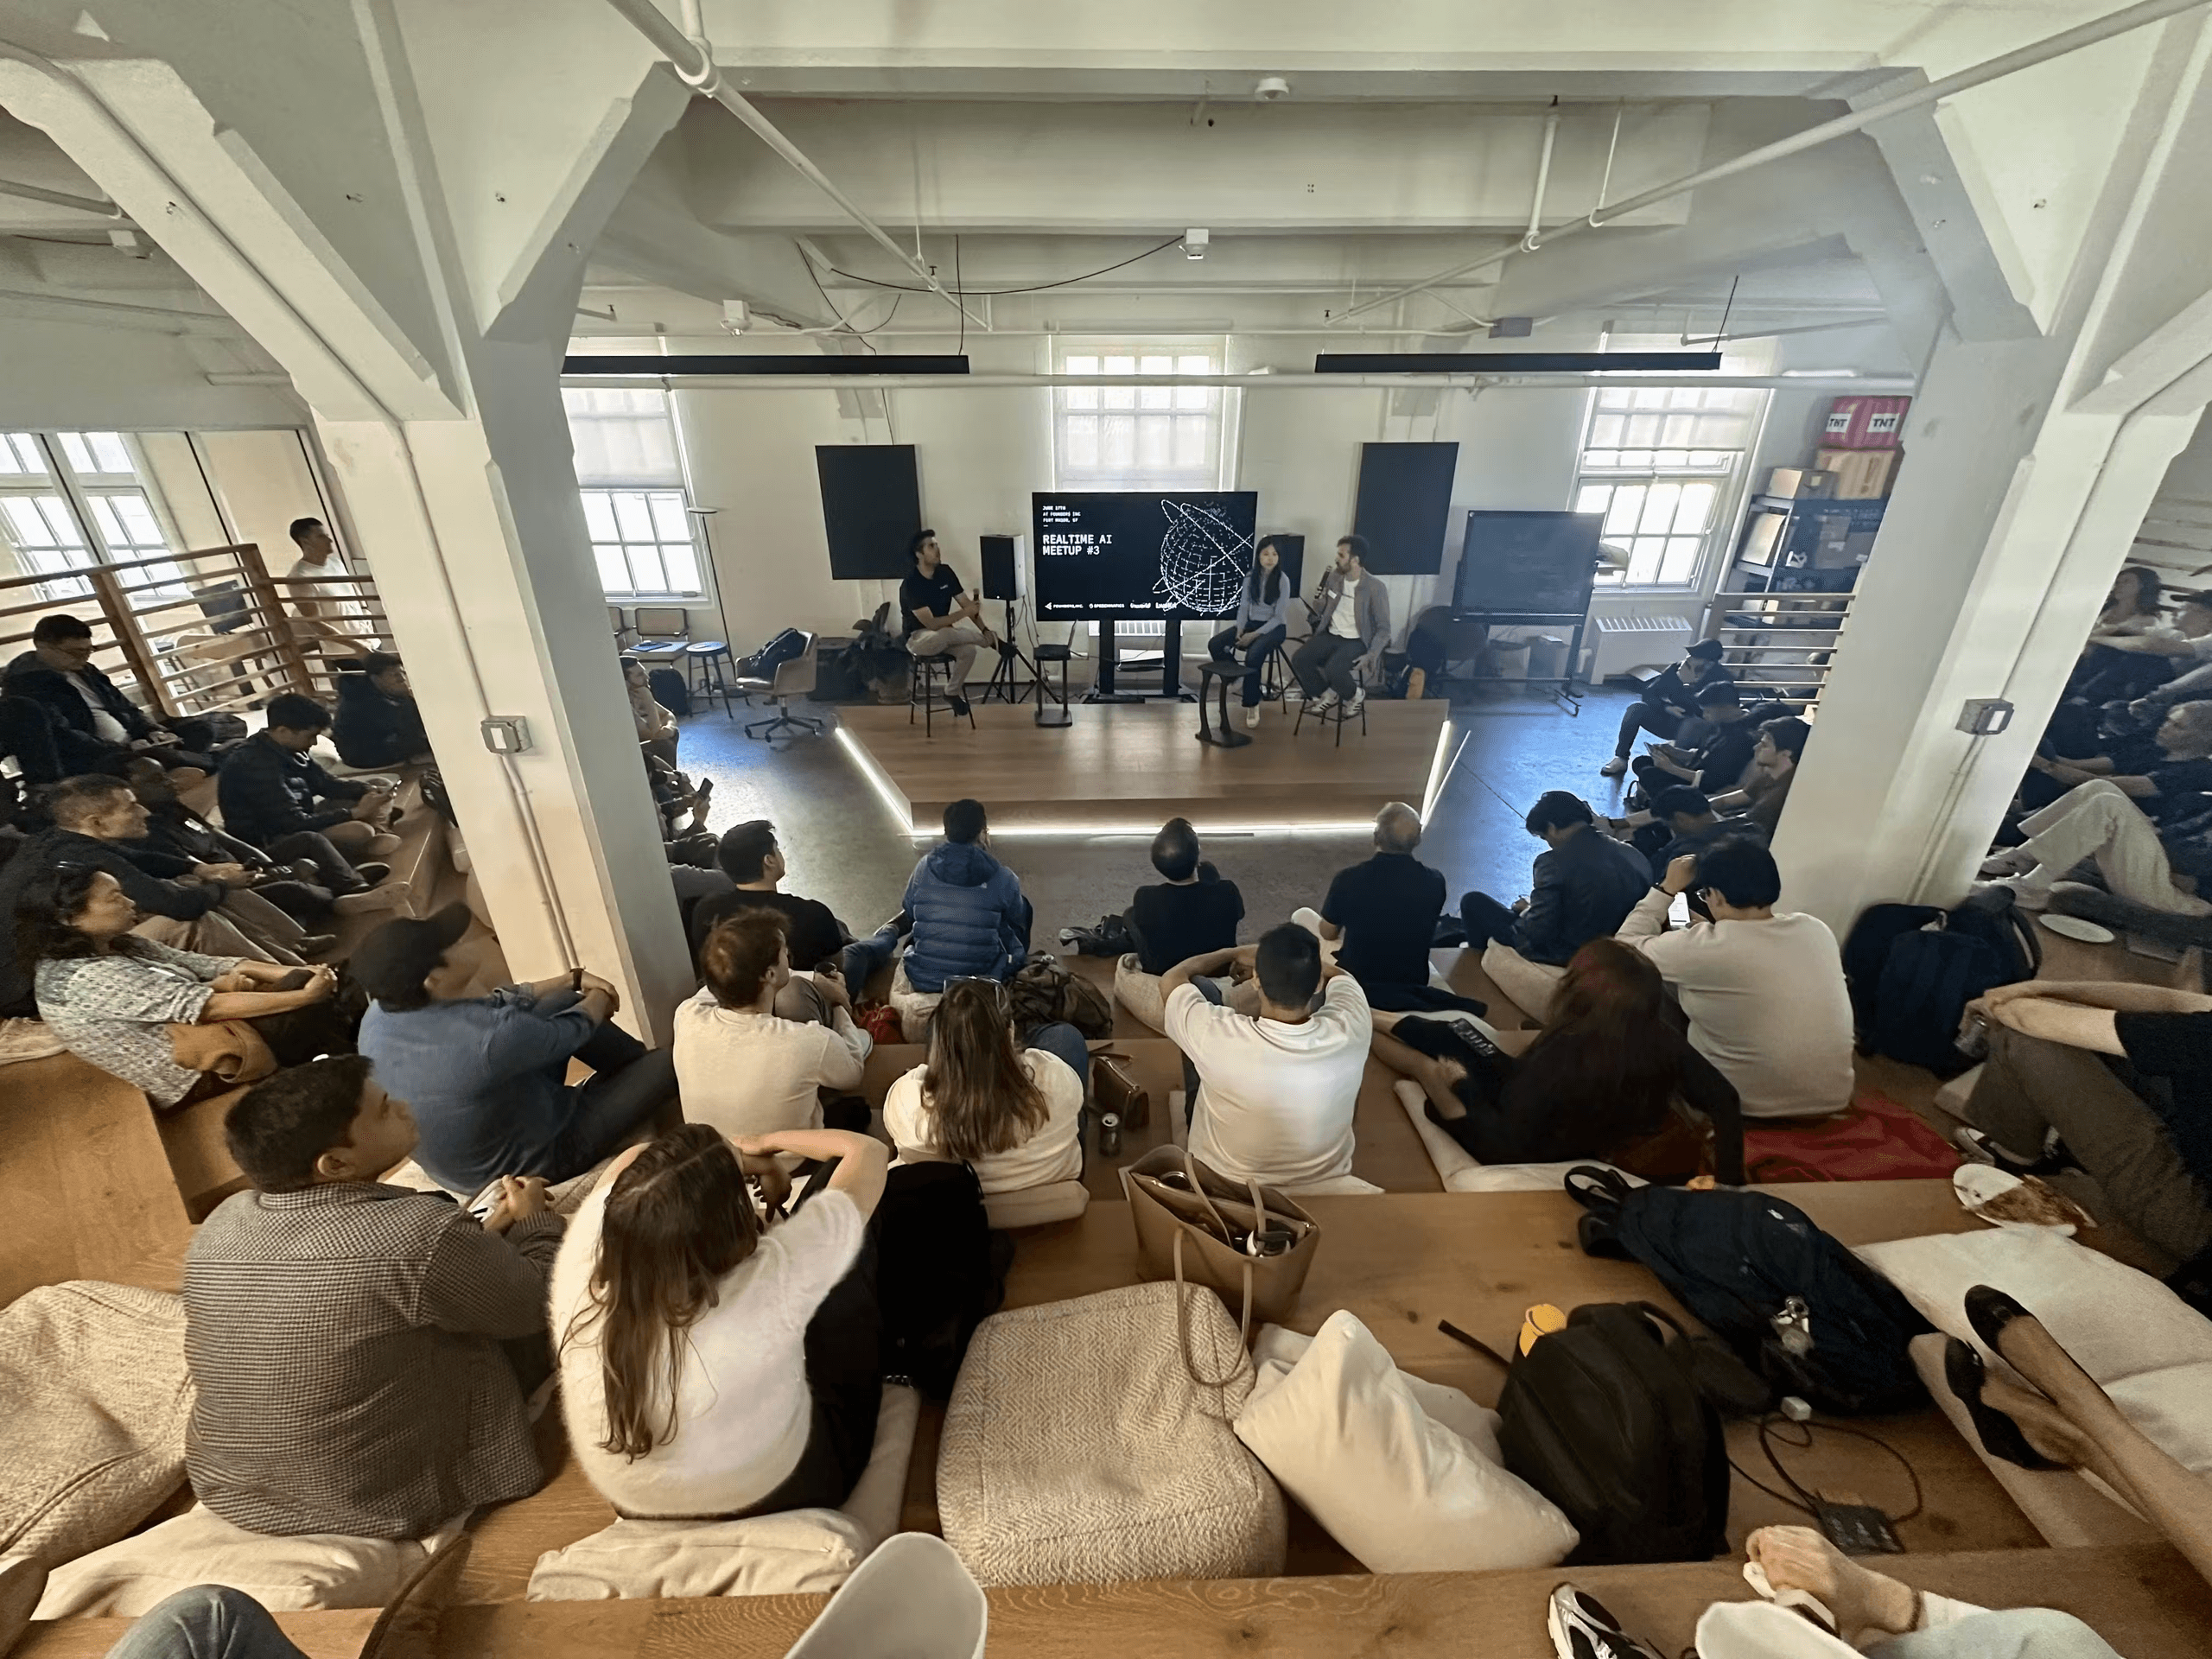
- Team rituals include social events like pizza parties watching World Cup